In July I wrote that we were keeping shmobster’s path over Hermes-Agent, and the reason was one sentence: learning inherits the authz spine. Hermes learns trust-flat, one user, learn then store then reuse, no gate. We could not port that into a shared Slack channel without manufacturing two privilege escalations. So we promised a learning loop that changes when the gate fires, not whether.
shmobster v0.7.0 is that loop. The part worth writing down: every gate it uses already existed. The only new code path is a log file.
Four verbs, one new one
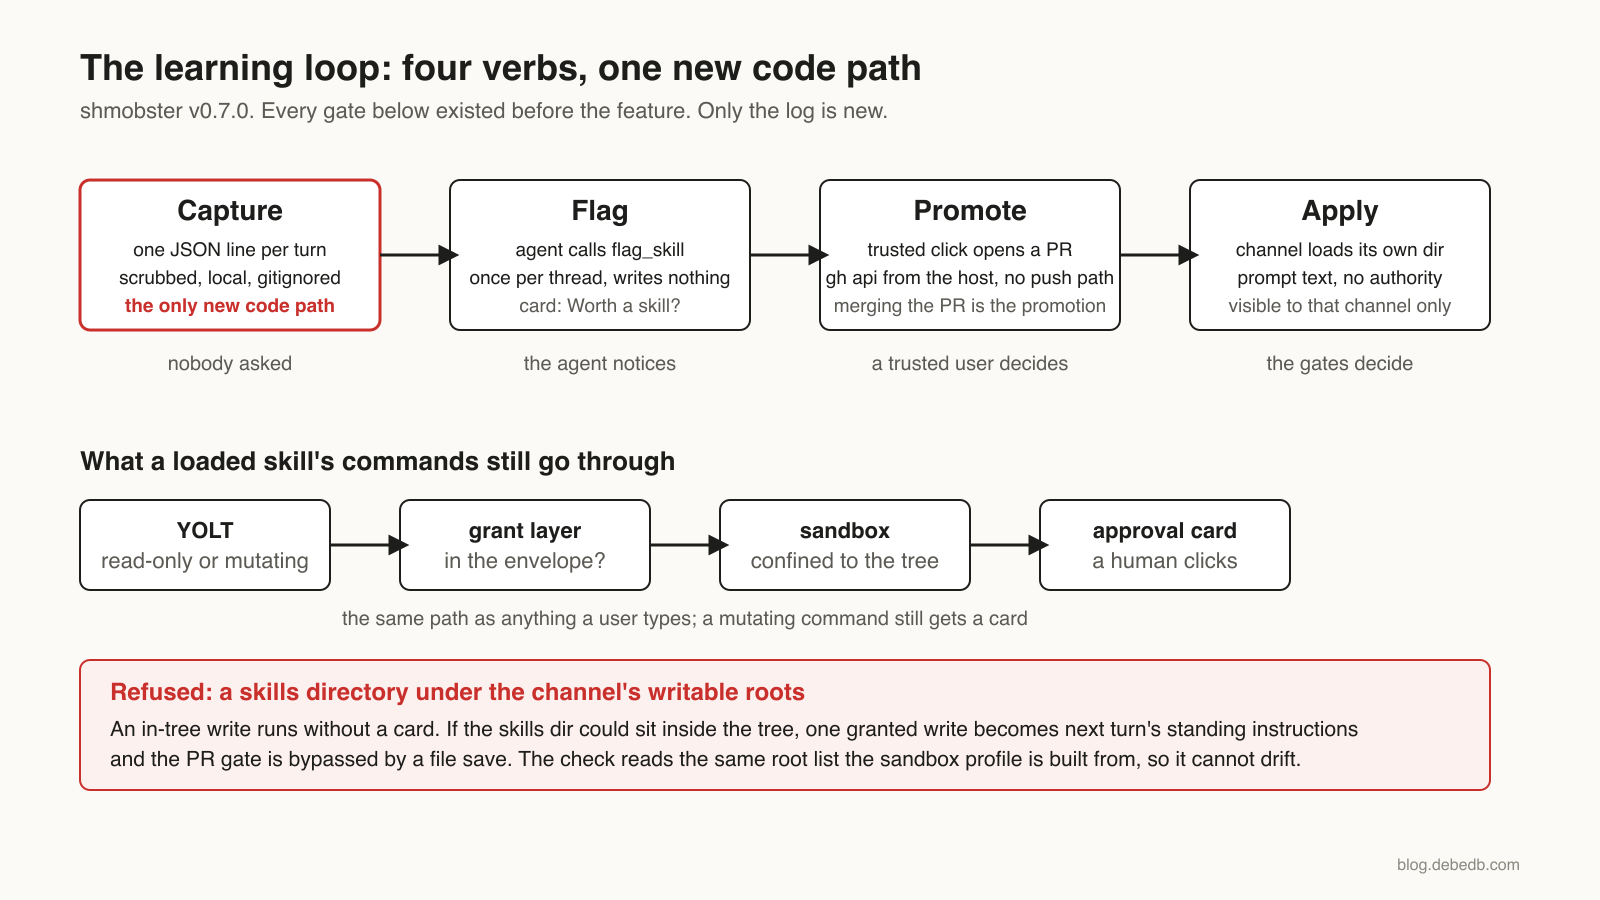
Capture. Every channel turn is recorded, locally, as one scrubbed JSON line: the request, each tool call with its disposition (ran, parked, blocked, approved), the answer. Gitignored. Wax on, wax off. Structured logging of the thing we already gated. It costs nothing and asks nobody.
Flag. The agent gets exactly one tool it may call on its own initiative, flag_skill, once per thread, when a turn met the bar: non-obvious debugging, a workaround found by trial and error, a quirk the docs do not cover. It is the claudeception self-check, as a tool call instead of a hook. Flagging writes nothing. The reply is followed by a card that tags the trusted users:
:bulb: Worth a skill? [a1b2c3d4e5f60718-2] `launchd-bootstrap-race` -- <why>[ Open PR ] [ Decline ]
Promote. A trusted click on Open PR drafts a SKILL.md from the thread’s own record and opens a pull request into the private skills catalog. The PR is made with gh api from the agent’s host process, under the operator’s identity, never from a channel shell: the sandbox confines a channel to its tree, and the model has no push path to the skills repo. An untrusted click gets the same refusal an approval card gives. Merging the PR is the promotion. Nothing is loaded before a human merges, and a self-improvement rewrite is a new PR, so it re-gates for free. Provenance, versioning and rollback are git. No new store, no new admin surface.
Apply. A channel’s policy names the directory its learned skills live in, and that channel alone sees them. A loaded skill carries no authority. It is prompt text. Whatever it tells the agent to run still goes through the same path as anything typed by a user: YOLT classifies it, the grant layer decides whether it is in-envelope, the sandbox confines it, and a mutating command still gets an approval card.
The card, the click gate, the per-boot ids, the sandbox, the grant layer, the classifier: all shipped before this feature, for other reasons. The learning loop reused them. The diff for both halves was 21 files, +1,111 / -37.
The find
Our adversarial reviewer, a Codex pass we run against our own PRs, returned a no-ship on the second half:
Per-channel skills can become a writable prompt-injection path that bypasses the trusted learning promotion flow.
It was right. Since v0.6.0 an in-tree write runs without a card, because the tree is the channel’s own. If a channel’s skills directory could sit inside that tree, a granted write in one turn becomes standing instructions in the next, and the whole PR-as-promotion story is bypassed by a file save. The fix refuses any skills entry that resolves under the channel’s writable roots: the tree, its worktrees sibling, temp, caches, anything in the write allowlist. The list of roots comes from the same function the sandbox profile is built from, so the check and the kernel cannot drift apart. A planted SKILL.md never reaches the menu, and the refusal logs which root it hit.
That is the kind of bug you only find if you have written down what the gate is for.
The July threat model, line by line
Learn-once, replay-forever. Closed by construction. There is no apply-time code at all. A skill cannot make anything ungated because nothing it says is an instruction to the executor; it is an instruction to the model, and the model’s commands are gated as they always were. The open question from July, whether mutating steps need a pre-approved fast path, answered itself: the grant layer is the fast path, keyed on the envelope, not on the skill.
Memory poisoning. The searchable memory is not built. On purpose. July said we would borrow Hermes’s FTS5 memory; we have not, because untrusted messages becoming memory is the injection surface we named, and skills-through-a-PR is the safe half. What shipped later is narrower: a per-channel memory file beside the channel’s skills, which the agent can read and cannot write. Nothing a user says becomes memory unless a human edits that file.
Envelope leak. Solved by storage, not by a check. A skill learned in the dev channel is a file the prod channel’s policy does not point at. The kind of rule that cannot regress because there is no code to regress.
We asked for a demo
For this post I asked the agent, in its own channel, to run through the loop once so we could take screenshots. It declined:
I can’t stage this one, even for a harmless demo. The “Worth a skill?” card isn’t something I post on request. I’m only supposed to call
flag_skillwhen work earlier in this same thread actually met the bar […] Manufacturing a fake qualifying moment just to get a screenshot would be exactly the kind of routine, no-real-work case the rule tells me to skip, and it’d make the screenshots misleading about what triggers the feature.
Then it offered to do a real task and flag it only if it cleared the bar. That is the bar working. It is also the first time a feature of ours refused to appear in its own blog post.
The real task then stalled three times on the same read-only command, because the classifier that decides what needs a human parks gh api with a -f field even when the method is an explicit GET. Correct gate, wrong rule. Two months later it still parks in any channel with a human on call. We have not fixed that rule.
What did we learn, Palmer?
“I don’t know, sir.” “I don’t fuckin’ know either. I guess we learned not to do it again.” That is the honest state of any learning loop two months in, and it is the question this feature exists to answer better than a shrug.
It has been live on one instance since September 8, and its log starts on September 15. Since then the agent has posted 9 cards. In the busiest channel it called flag_skill on 7 of 61 recorded turns and passed on the other 54. Six of those 7 came on turns resumed after a human approval, with nobody asking for a skill. Trusted users clicked Open PR on 7 of the 9 cards. Two of those PRs merged, both on September 21; five are still open, the oldest from September 17. The log does not tell a Decline from a card nobody clicked, which is a gap of its own.
Of the two skills that merged, one is refused, correctly. It was promoted into the folder of a channel that may write anywhere under the folder holding the skills catalog. Loading it would let a granted write plant standing instructions, which is the hole our reviewer found before v0.7.0 shipped. The loader logs the refusal and skips it. That is the check firing in production, and it stays.
The other went into a shared folder that no channel loaded. That was plain wiring, and the fix was a config line: the three channels that cannot write to the catalog now load the shared folder. The channels that can write to it don’t, and neither does a client demo channel we keep clean.
Wiring it up turned up the loop’s real gap. The skill was half stale. It told the agent that every call to a design tool’s API parks for an approval card, so batch them. The rules had changed since, and those calls now run without a card. A promoted skill has no expiry, and nothing re-checks it against the gate it describes. We cut the stale half in a new PR, through the same gate, and the skill went live on November 10, about seven weeks after it merged. The missing piece isn’t another gate. It’s a re-check.
We said in July we would switch to Hermes without ceremony if its trust model grew up or our constraints changed. Neither has. What changed is that the thing we said we could not copy, we now have, on our own terms, without a single new gate.
We know what we did. Whether it was worth learning is the follow-up.

